AI Content Model Collapse and Its Effect on Source Trust
Trusted sources now matter more than owned content in AI search results.
November 4, 2026
AI content model collapse is also a source-trust problem. As synthetic text feeds both model training and live retrieval, AI answer engines are under growing pressure to tell original information from independent sources apart from recycled output. For brands, the strategic consequence is a shift from publishing more owned content to earning a place in sources whose authorship, evidence, and editorial independence make them worth citing.
How model collapse works and why the web is already inside the loop
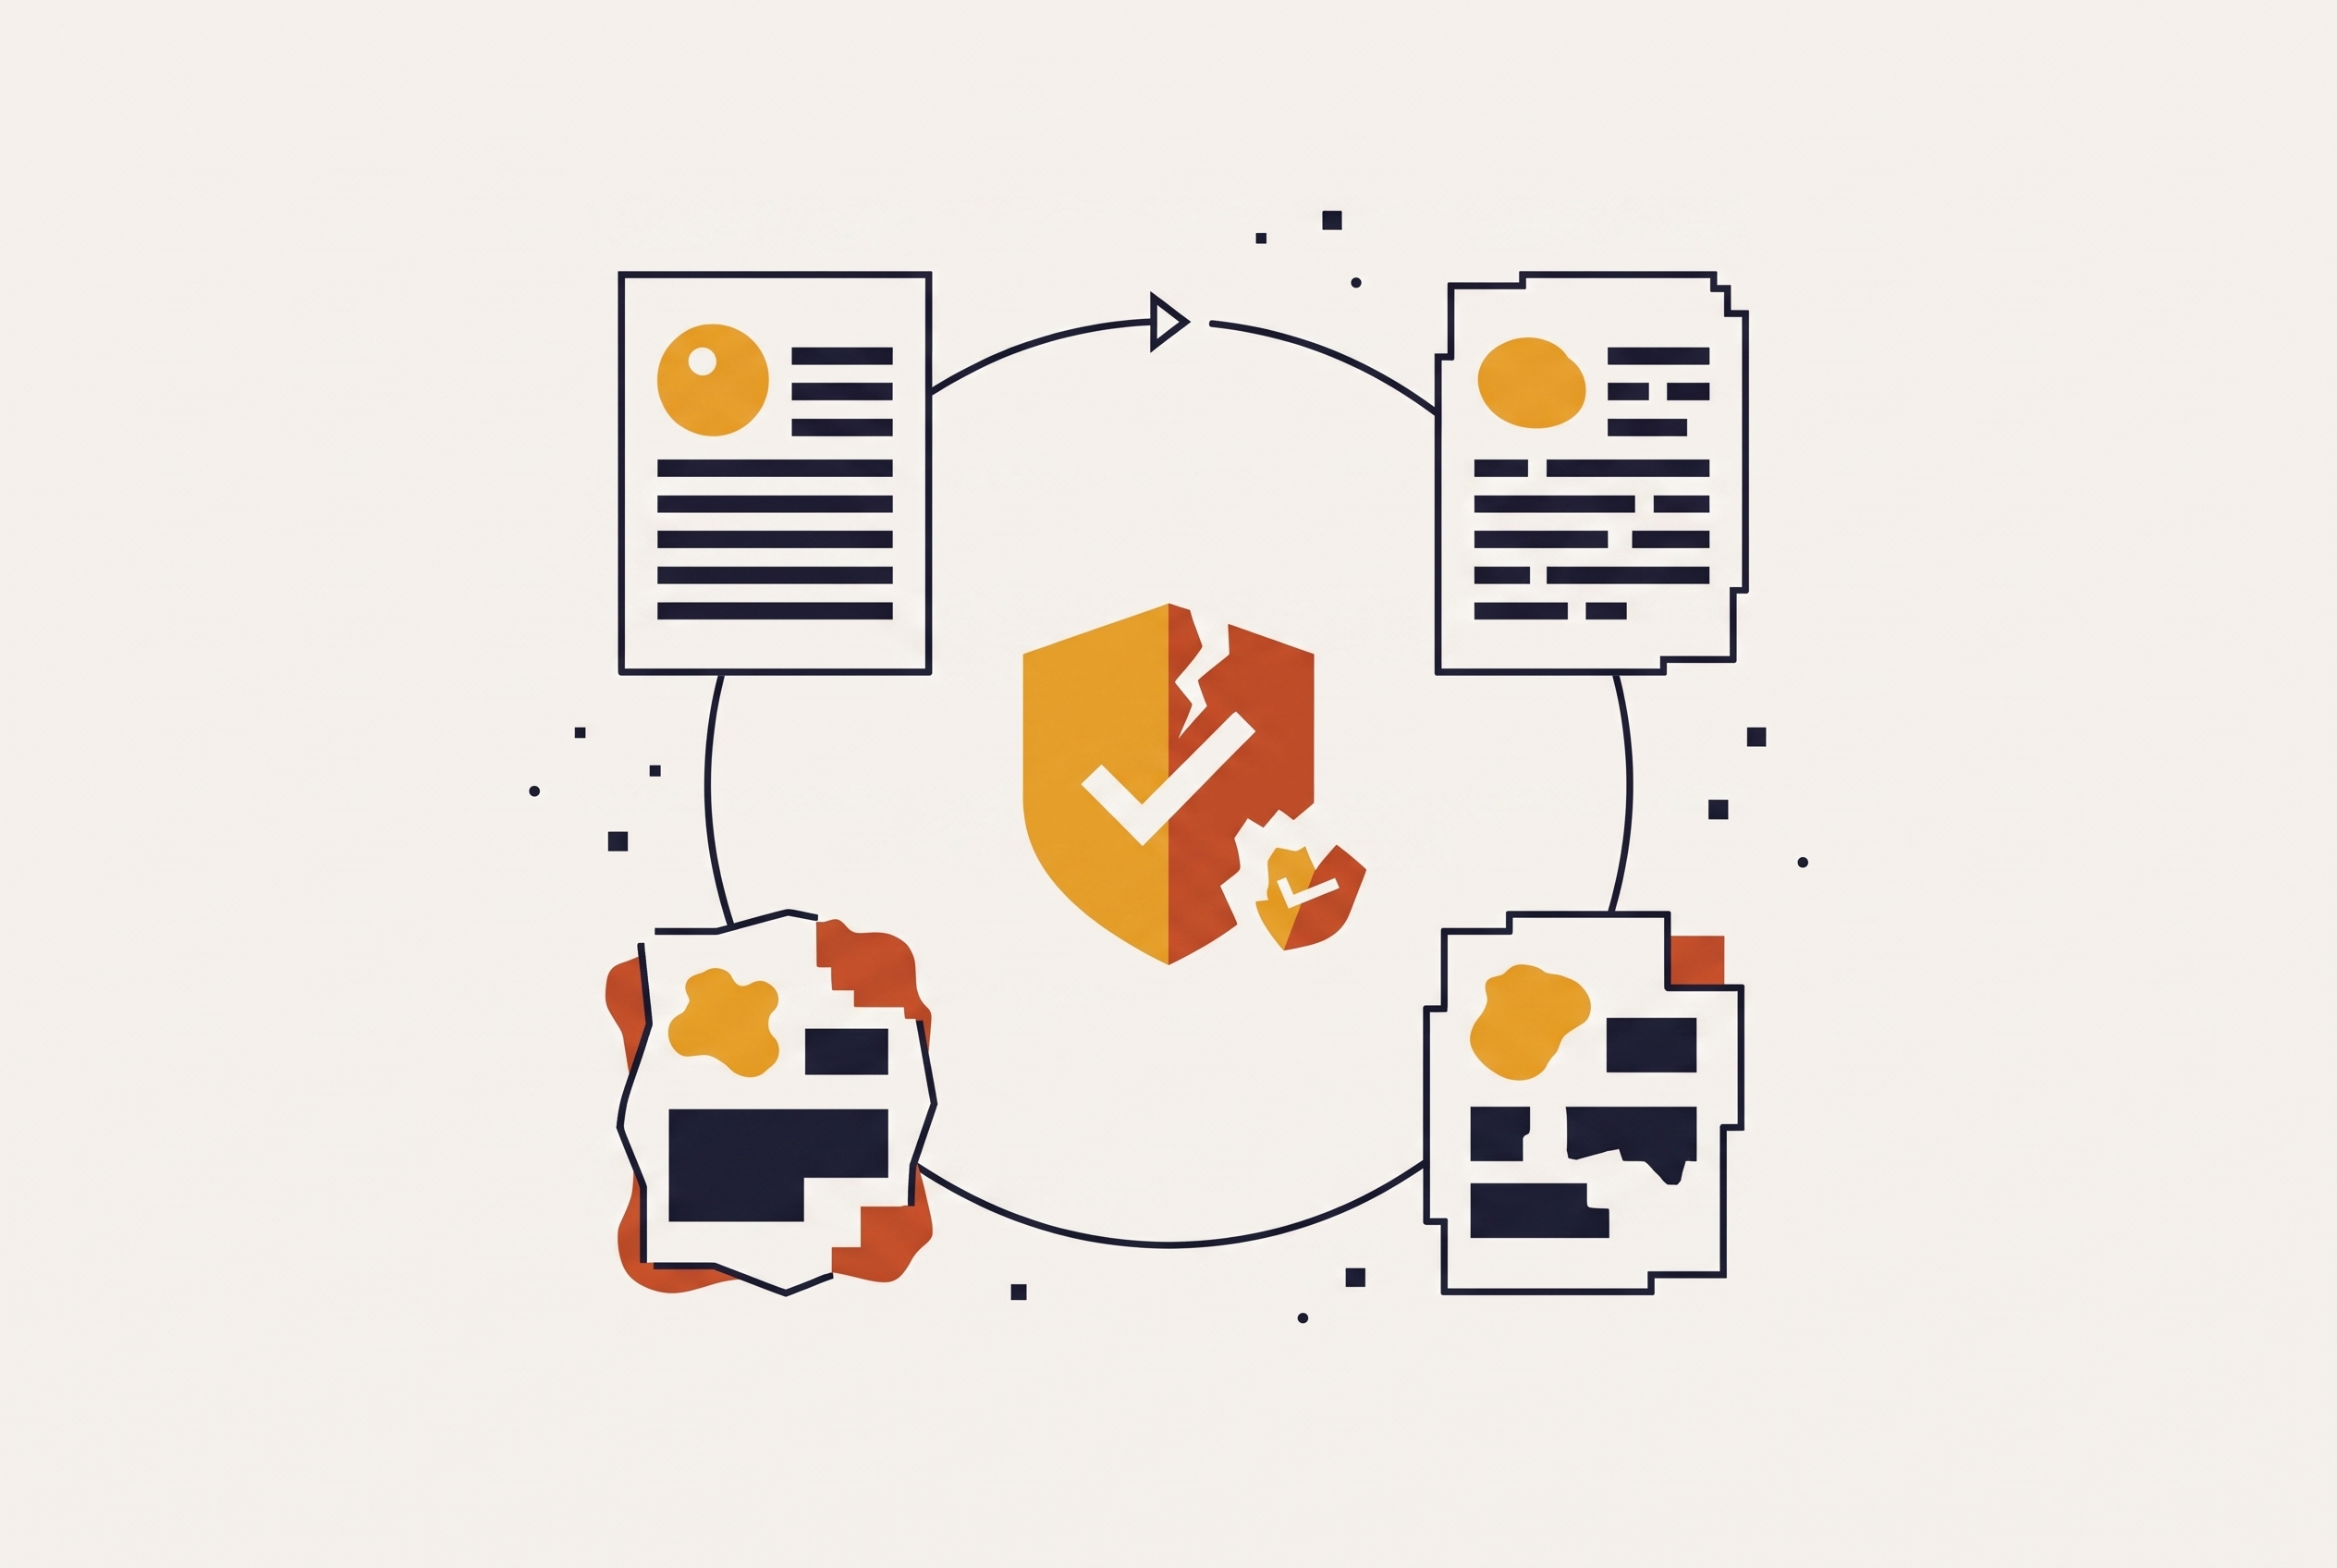
A model generates text, that text enters the web, and a later model learns from it as though it were original evidence. Each turn can reproduce errors while narrowing the range of language and ideas represented in the training data. The output then becomes input again. This is the mechanism of model collapse, in which recursive training on generated material reduces distributional diversity and pushes models away from real-world factual accuracy.
The web is already inside this feedback loop. Spennemann's 2025 large-scale analysis estimated that 30–40% of all active web text originates from AI-generated or AI-edited sources. At that scale, a web crawl cannot reasonably be treated as an uncontaminated supply of human writing. Satharasi & Iyengar (2025) document a steady rise in semantic similarity in large-scale text corpora from 2013 to 2025, providing evidence of narrowing linguistic diversity before full collapse is reached. Deliberate provenance controls become necessary because the origin of the text cannot be inferred from its availability.
Gambetta et al. show that model collapse includes a measurable decline in commonsense inference accuracy alongside a loss of diversity. Myakala et al. (SynthSentry) note that grammatical, confident output persists after factual accuracy has begun to fall. Checking how text reads thus does little to guard against contamination, and any large web crawl must now be treated as contaminated, though how much is unknown. Fluency survives the degradation that makes the information less dependable.
Why model collapse creates a parallel crisis for AI answer engines, not just AI trainers
An answer engine does not need to retrain on synthetic content to become exposed to it. Its retrieval pipeline can return increasingly homogeneous, synthetic, or adversarially optimized pages while the model's weights remain unaffected. The immediate answer may still be accurate. Yet its source base has narrowed, making retrieval collapse a distinct problem that can remain difficult to see until the effects compound.
For content marketers, this creates a self-defeating incentive. AI-written articles meant to gain AI search visibility often have little of the original data and specific claims that make sources worth citing. As more of that material enters the web, answer engines face stronger pressure to discriminate against the flood. A brand's visibility consequently depends not only on whether its pages can be retrieved, but on whether they provide something the engine can trust enough to attribute.
What AI answer engines actually use to decide which sources to cite
An answer engine rewrites a query into multiple searches, retrieves candidate pages, then writes an answer and attaches citations to specific statements drawn from those sources. Findability gets a page into contention. Quotable material gives the system something usable, while checkable claims support attribution. A page can succeed at the first requirement and still fail at the others.
Page structure helps make those claims accessible. Pages with question-phrased H2 headings receive more citations than unstructured prose, and answer capsules at page openings raise citation rates. Ordered and unordered lists also appear in the large majority of AI Overview responses. Content with meaningful new information also has an edge over older pages ranking in organic search, because its recency signals that editors are keeping it up to date.
Authorship supplies a different kind of evidence about the source. Pages with a named author, title, and linked biography get far more AI citations than the same kind of content with no named author. The distinction is not simply professional presentation. A byline and biography give the information a traceable origin, making authorship a provenance marker as well as a credibility signal.
These signals do not operate identically across platforms. ChatGPT and Perplexity draw from substantially different source pools, with only a small fraction of cited domains appearing on both. Category context therefore shapes which signals dominate. Across that variation, consistent mentions in independent sources strengthen a brand's credibility more than a mention in one source, however authoritative. Corroboration gives the engine evidence beyond a single publisher's assertion.
Why vendor-authored content is structurally discounted by AI systems
Stacker and Scrunch studied hundreds of prompt-platform combinations across five AI platforms and found that citation rates for the same article rose sharply when third parties published it. Brand-only content achieved roughly one-quarter of what earned distribution achieved. The text alone did not explain the difference. In a meaningful share of answers, the engine cited the third-party version without citing the original brand piece at all. The publisher became the credible attribution point for information that had originated elsewhere.
Brand-owned content is designed to communicate the brand's position, while answer engines must decide whether that position has support beyond the interested party. A single brand page supplies one source. When the same claim appears across hundreds of independent publishers, systems can treat those appearances as corroborating points. Those corroborating points help explain why the publishing context changes citation behavior.
Earned third-party sources account for the large majority of non-paid citations across major AI engines. Brand sites still appear in a sizable minority of responses, so owned content still has a part to play. An accurate product page and an independent comparison can both be eligible while serving different evidentiary purposes.
Google Search Central states that there are no additional technical requirements for a page to appear as a supporting link in AI Overviews or AI Mode beyond being indexed and snippet-eligible. That addresses an important but narrower question. Indexing eligibility allows a page to appear but leaves its selection over competing sources uncertain. Standard SEO can meet the entry conditions without resolving the independence and corroboration disadvantages of vendor-authored material.
How off-site presence and third-party publication change a brand's position in AI answers
A dense off-site presence changes the evidence available about a brand. Brands with strong third-party visibility are substantially more likely to appear in AI search than those relying on owned content alone. The placement also influences the result. The vast majority of brand mentions that earn AI citations come from listicles, comparison pages, and review roundups, and brands near the top of those pages get cited more often than those farther down.
The relationship differs from the backlink logic of traditional SEO. Brand mentions across the web correlate with AI citations at a rate roughly three times stronger than backlinks. Selection remains uncertain despite that correlation. It still suggests that brands should track where relevant sources mention them and how those sources describe them, as well as links to their domain. The question shifts from which pages rank to which pages supply the answer.
For practitioners, the reverse citation strategy makes that shift concrete. A brand finds the third-party pages that AI platforms already cite for queries in its category, then contacts those publishers to seek mentions on those pages. This starts with observed citation sources rather than a general publisher list. It also makes platform differences actionable, since a source used by one answer engine may not belong to another's citation pool.
Well-indexed, well-structured pages provide the entry ticket to retrieval pipelines, while AEO addresses the signals that govern attribution to retrieved material. Off-site work still needs to go hand in hand with owned pages that engines can access. It expands the set of sources through which the brand can become part of an answer.
What editorially independent publication looks like as a structural asset, and why it works against model collapse pressure
A standalone editorial publication gives a brand an off-site source it can keep up over time, beyond a one-off placement. Its own domain, masthead, named authors, and original content give it an identity of its own as a publication. Those elements are not sufficient as surface decoration. Their value comes from the editorial operation behind them, including structured articles, inline sourcing, a consistent publication cadence, and a domain-specific voice. Together, they make the origin and substance of the information easier to assess.
That architecture addresses the pressure created by synthetic contamination. An answer engine seeking original information needs more than fluent prose or the appearance of authority. Traceable authorship and editorial consistency provide evidence about how a source was produced. A publication that operates independently and does not read as a brand channel fits the category of source that systems are under pressure to prefer.
Phantomstory builds this form of asset as independent trade properties. Each phantom publication has its own domain, name, masthead, editorial voice, and original illustrations, designed to sit within trusted citation pools without reading as brand-owned content. Those features map to the structural requirements of a recognizable editorial source.
A brand described with consistent attributes across third-party sources is more citable than one whose descriptions conflict, because corroboration depends on agreement about the entity. Citation visibility is also unstable. Around 50% of brands that lose AI visibility resurface within two runs, with stronger off-site signals correlating with faster return. Publications therefore require continuing editorial work, since citations erode when output stops.
What brands should actually audit and change, given the model collapse pressure on source trust
Brands should find out which third-party pages each major AI platform cites for relevant queries in their category, then check whether those pages mention them. Category comes before distribution strategy. There is no universal top citation source, and the dominant platforms and preferred source types vary by vertical. An audit that overlooks those differences can confuse being seen widely on the web with being in the sources that shape answers.
The same audit should examine authorship and provenance as operational controls. NHI Mgmt Group's analysis of model collapse governance frames provenance as a release gate for AI training pipelines. Applied to content strategy, that logic makes traceability and human authorship part of publishing quality. A named author is useful because the work has an identifiable origin. Editorial independence similarly needs to describe how the publication operates.
Measurement should follow the change in objective. Rankings, impressions, and clicks no longer provide a sufficient account of performance when the desired outcome is inclusion in an AI-generated answer. Brands then need to measure brand mentions, citations, AI referral traffic, and share of voice across answer engines. These measures distinguish a page that is discoverable from a source that influences the answer. They also keep attention on off-site evidence that owned-site analytics alone cannot represent.
The highest-leverage investment is therefore a durable base of independently citable sources. A fleet of independently operated niche publications can provide that base when maintained with editorial discipline, original work, and consistent entity descriptions. Ownership alone does not create the advantage. The asset is the publishing operation that produces information with a traceable origin and a purpose beyond repeating a vendor's claims. Brands that build on those terms are not simply chasing citation behavior, but positioning for a structural shift in how information earns trust.