Phantom Publication Performance Across a Fleet of Five Domains
AI now rewards citations from independent sources, not brand websites, reshaping visibility.
September 30, 2026
Buyer research increasingly ends inside an AI-generated answer rather than at a clicked link, and that shift has quietly rewritten the rules of brand discovery. A large majority of consumers now say they plan to use AI for shopping more often. The destination that used to be a webpage is becoming a synthesized paragraph with no address bar attached. A brand's appearance in that paragraph now depends on factors unrelated to old-fashioned search rank. Ahrefs' March 2026 analysis of AI Overview URLs found that a substantial share of cited pages never appeared in the top 10 organic results at all, so ranking well and getting cited are only loosely related events. A page can dominate a search results page and still be invisible to the AI system answering the same question.
The reason traces back to how these systems decide what to trust. AI engines weight editorial independence over domain ownership, so a brand page asserting its own superiority starts the race with a structural handicap against a third party simply describing that same brand. OtterlyAI's State of AI Search research found that 95% of all AI citations originate from third-party websites. A brand's own domain, for citation purposes, is nearly irrelevant to the pool these systems draw from. Muck Rack and Generative Pulse's May 2026 dataset, built from tens of millions of citations, reinforces the same pattern from a different angle: earned media accounts for the dominant share of AI citations, while paid or advertorial content accounts for a negligible fraction. Two independent datasets, two different methodologies, one conclusion. Systems built to synthesize trustworthy answers treat self-interested sources as exactly that, self-interested, and downweight them accordingly.
Large language models generate answers conditioned on retrieved sources, and when a brand is not embedded in that retrieved context as the recognized owner of a claim, its content can still shape the answer without ever earning a citation. A brand's language, framing, even its original research, gets absorbed and paraphrased, but the credit lands on whichever third-party source the model trusted enough to name. A company can write the best page on the internet about its own product and still watch a competitor's mention in a trade publication get the citation instead. Good content is not the variable that fails here. Source independence is.
How AI retrieval works (and what it means for a publication that wants to be cited)
Three sequential steps decide the outcome: retrieval, extraction, and attribution. A publication has to clear all three, and doing well at only one leaves it invisible regardless of how strong that one step is.
Retrieval comes first, and it is a gate, not a ranking. Crawlers need explicit access to a site, and different bots serve different purposes: OpenAI's OAI-SearchBot handles search citation while GPTBot handles training, so blocking either one removes a publication from that half of the citation pipeline entirely. The consequences of getting this wrong are not theoretical. A single robots.txt file decided that outcome.
Extraction is the second gate, and it changes what "good content" even means. The unit an AI system cites is not a page, it is a fragment. Anthropic's own web search documentation shows citations carrying up to 150 characters of quoted text. A page answering one question cleanly in a single paragraph will outperform a page that spreads the same answer across four. Position matters as much as concision. A large share of citations come from the opening portion of a page because the retrieval pipeline reads top-down. Answer-first writing is a mechanical requirement of how these systems extract text, not a stylistic preference an editor might choose to ignore.
Attribution is the third gate, and it behaves like a filter that never stops running. Content that goes stale becomes less likely to be retrieved during pre-answer sourcing, even when the underlying facts remain accurate. Brands that lead in answer engine optimization tend to update their content on a quarterly cadence at minimum, treating freshness as an ongoing maintenance cost rather than a one-time publishing decision. Layered on top of all three gates are the trust signals a system weighs when it finally chooses which source to name: named authorship, visible sourcing, clear publication dates, internal consistency, and corroboration across other pages. These are the same signals that separate an independent editorial publication from a brand asset making claims about itself.
None of this plays out uniformly across platforms, either. Perplexity references community platforms in the majority of its answers, while Gemini does so far less often, per AirOps' State of AI Search report. A publication built around a single domain is making a single bet on a single platform's retrieval behavior, and that bet does not transfer cleanly to a system with different sourcing habits.
The Stacker-Scrunch data on third-party distribution and citation rate
The Stacker-Scrunch study is the clearest controlled comparison available: identical content distributed through different channel types produced dramatically different citation rates, with domain authority and editorial independence as the variable, not content quality. The study covered a set of stories across multiple clients, querying thousands of prompts across eight AI platforms. Because the content itself stayed constant across conditions, the study isolates a single variable: where the content lived and who published it.
The results were not subtle. Citation rates for content published on a brand's own site were substantially lower than citation rates for the identical content distributed through third-party news outlets, and a broader March 2026 follow-up replicated that lift with a sizeable median gain. Cross-platform coverage very nearly tripled at the median when the same story ran through third-party channels instead of owned ones, a metric Stacker calls "coverage breadth" and treats as a core measure of generative engine optimization performance. Distributed versions were also substantially more likely to be the sole source powering a story's AI visibility, compared to the brand's own website carrying that role.
One additional finding from the same dataset deserves attention because it shapes everything that follows in this argument. A story explaining how no-preset-spending-limit credit cards work performed well, because it matched a specific, real buyer question. A companion story framed around the broader idea of "understanding business credit cards" underperformed, because the framing was too broad to match any single query a buyer would actually type or speak. Specificity of topic to buyer intent, not just distribution channel, determined whether a story earned its citation.
An objection surfaces naturally at this point: the Stacker-Scrunch study measured earned media distribution through existing third-party outlets, not a fleet of independently built phantom publications, so the comparison might not transfer. The mechanism, however, is identical either way. AI systems weight the authority and independence of the citing domain over the origin of the content sitting on it. A phantom publication built on its own domain, with a genuine editorial identity, name, masthead, and voice, replicates the exact trust signal that third-party news distribution produces. A brand can build and operate that signal directly, at scale, under conditions it controls.
A fleet of five domains outperforms a single publication
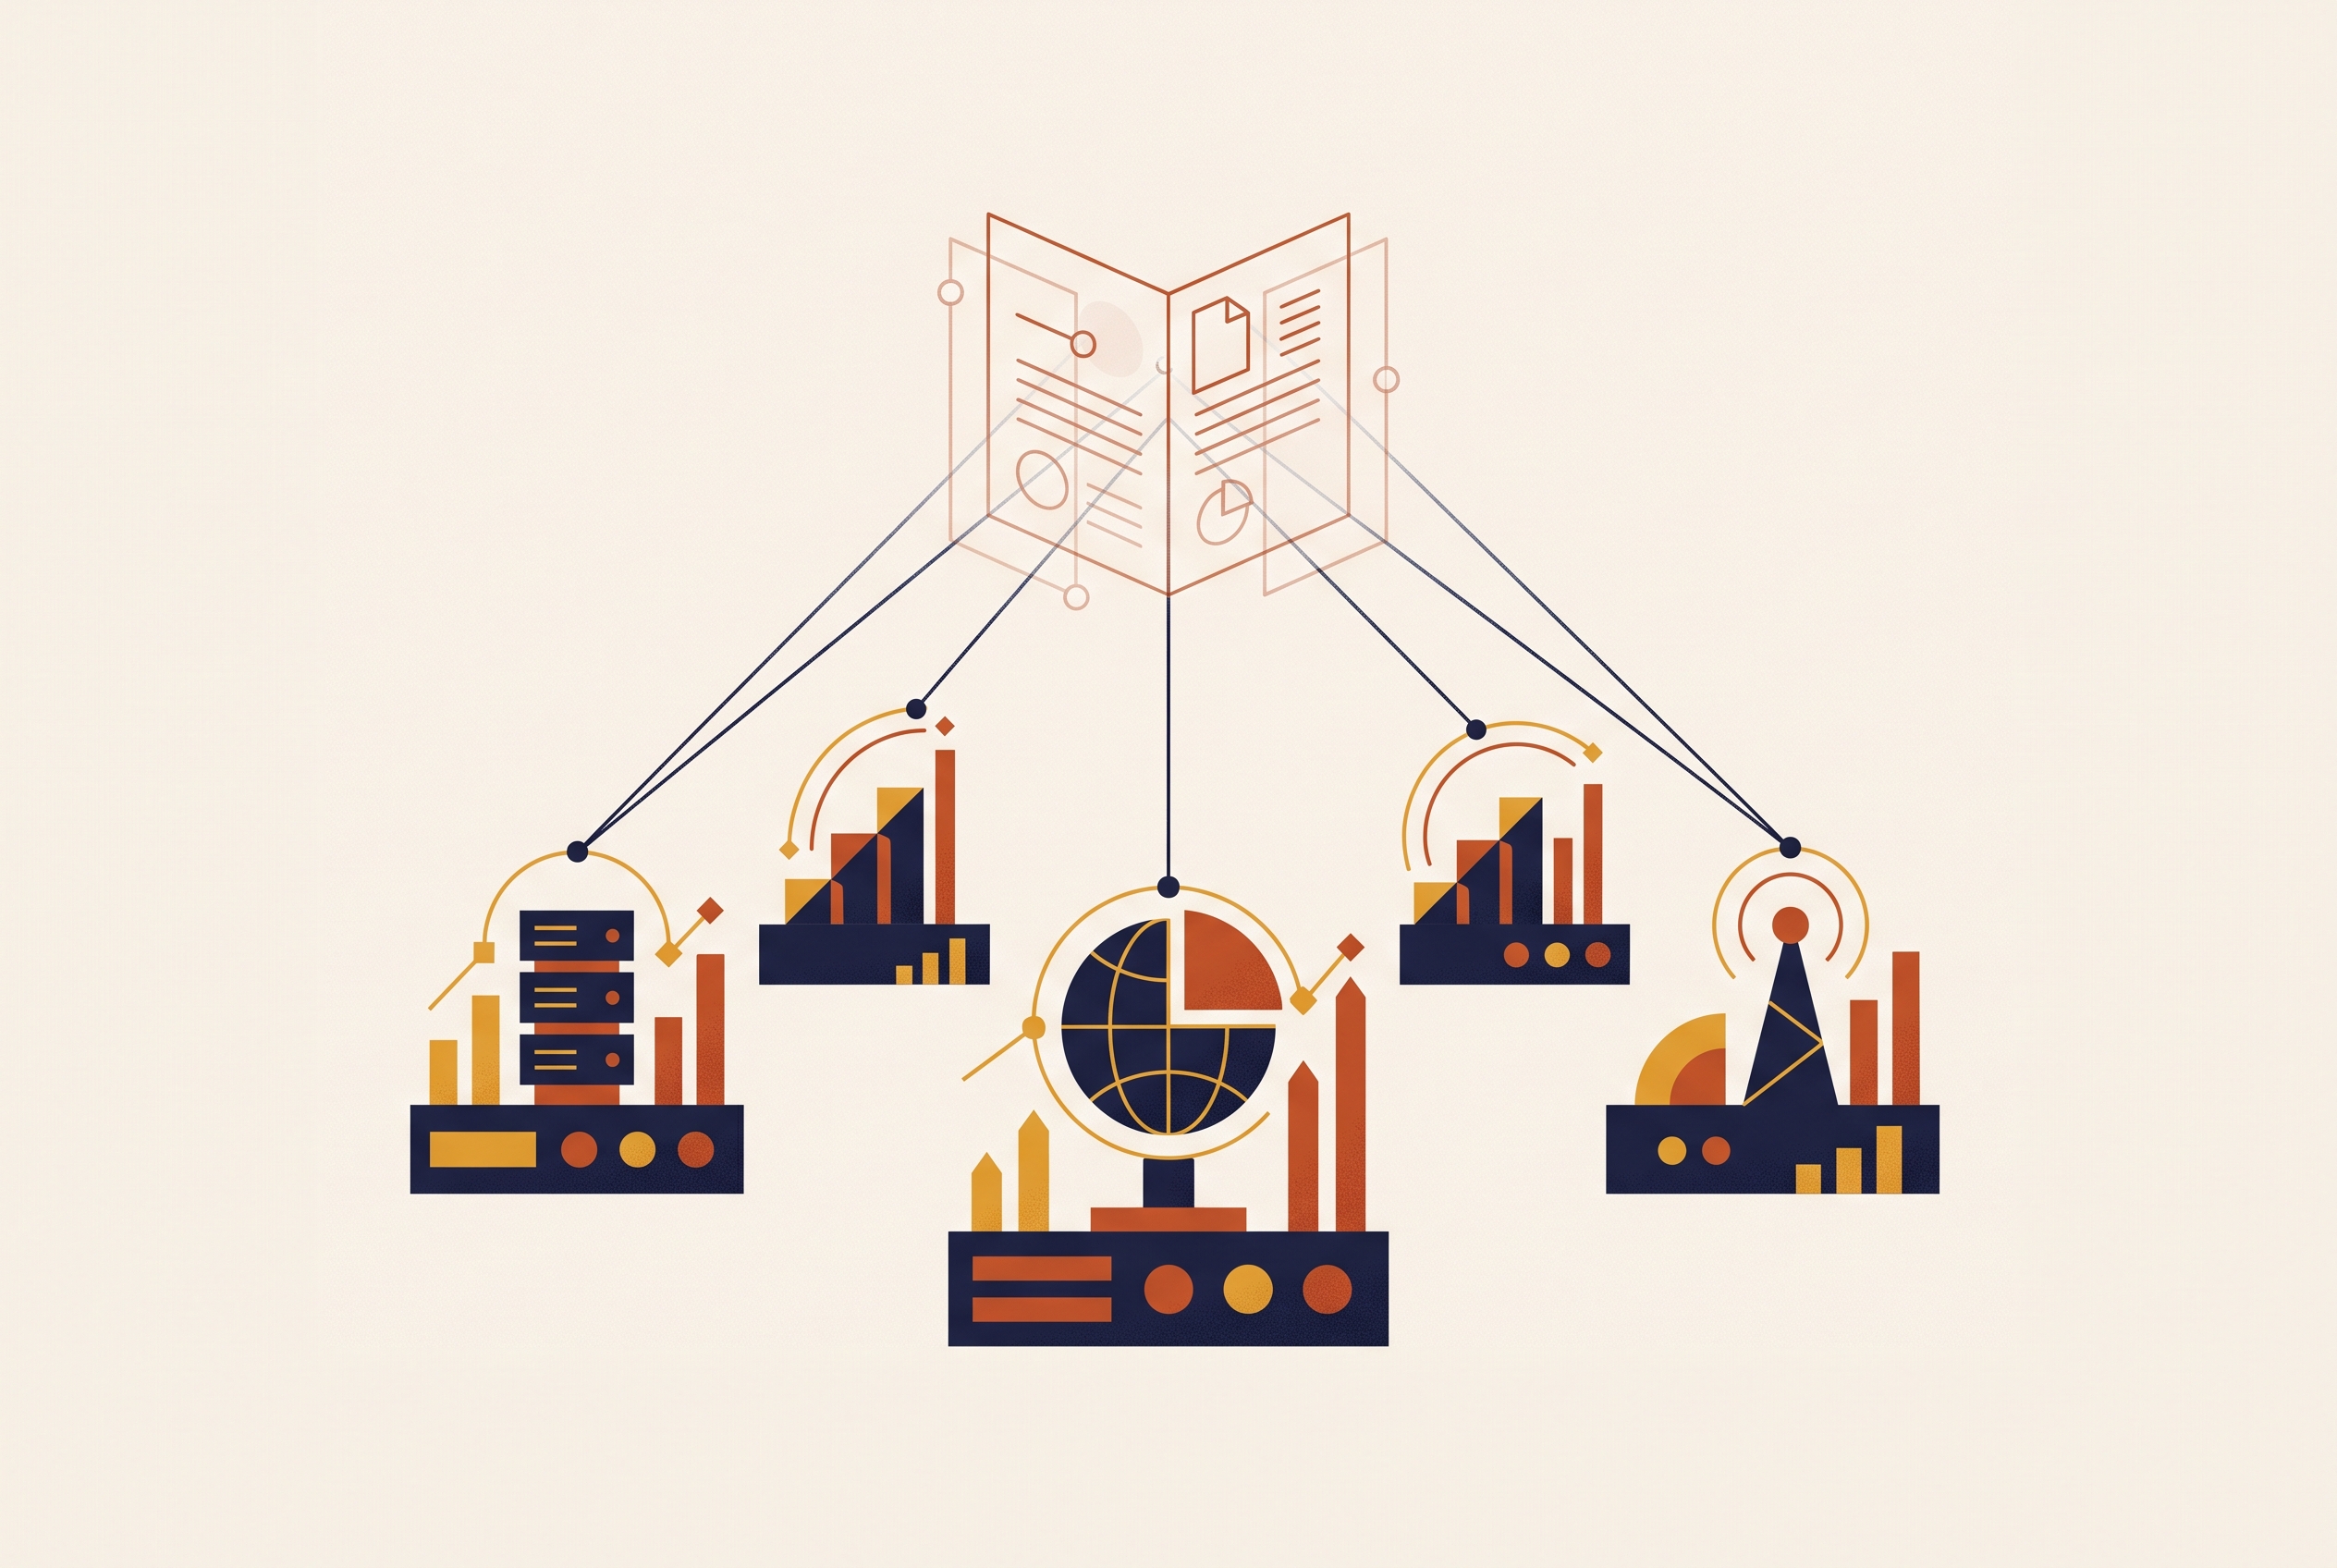
A fleet of independent publications solves what a single publication cannot: consistent coverage across platforms. A fleet of topically distinct independent domains does not just multiply the output of one publication, it creates citation redundancy across different AI platforms, different crawler indexes, and different topical trust clusters at the same time. That is a different kind of asset than a bigger version of the same one.
The platform variation established earlier makes this concrete. A single publication indexed primarily by one crawler is a single bet on that crawler's behavior. Five publications, each indexed independently across different AI crawlers, create five separate entries into citation pools that overlap in places and diverge in others. Losing ground on one platform does not collapse the whole structure, because the other four domains are not exposed to the same failure. AirOps' 2026 State of AI Search report backs this with a broader finding: brands that appear frequently across a wide range of credible, high-quality sources build a stronger signal in how a model understands their category, and that breadth of presence, not depth invested in a single domain, is what produces the advantage.
Breadth changes something more subtle than visibility, too. AI models do not simply register that a brand exists somewhere in their training data, they absorb the context surrounding every mention of it. A brand described as reliable or category-leading across five independent editorial sources gets represented differently inside a model than a brand described that way on a single domain, according to research from trysight.ai. AirOps' report reaches a parallel conclusion from the citation side: brands with a strong off-site presence are substantially more likely to earn visibility in AI search than brands relying on owned content alone.
Topical structure inside the fleet does real work here, too. When each publication owns a distinct niche query cluster, one covering supply chain, another covering procurement technology, each domain builds citation authority inside its own topic space rather than competing against its sibling domains for the same queries. More specific content maps to more specific buyer questions, echoing the finding the Stacker data surfaced about the no-preset-spending-limit story outperforming the generic one.
There's a longer horizon to this, too, one that outlasts any single query. Beyond real-time retrieval, a fleet of independent editorial sources accumulates a footprint inside the training data itself. Five sources discussing a brand in a consistent, positive register, over time, progressively embed that brand as the authoritative entity in its category for future model training cycles. It is closer to an infrastructure decision than a citation tactic, the kind that compounds the longer it runs and the more domains contribute to it.
The content and structural signals that determine which phantom domains get cited
Not every domain inside a fleet performs equally, and the gap between the domains that get cited and the ones that don't traces back to a specific, repeatable set of properties. Content that opens with a direct response to a specific buyer question consistently outperforms content that saves its answer for the third or fourth paragraph, lining up with the top-of-content citation bias and the 150-character fragment unit described earlier.
Named authorship carries real weight in this system, not just as a courtesy to readers. AI systems weight author credibility, sourcing transparency, and internal consistency when deciding what to trust, so a publication with a named editorial staff, bylined articles, and visible sourcing practices earns a higher trust weight than an anonymous content property publishing under no one's name.
Freshness operates as a hard requirement rather than a nice-to-have. Outdated content gets filtered out at the retrieval stage regardless of how authoritative it once was, so each domain in a fleet needs a publishing cadence that keeps its content current, matching the quarterly-minimum standard that leading AEO brands maintain.
Crawler access is a technical detail with outsized consequences. Each domain has to explicitly permit the AI search crawlers relevant to its target platforms, OAI-SearchBot for ChatGPT search, PerplexityBot for Perplexity, and a misconfigured robots.txt file quietly disqualifies a domain from that platform's citation pool without any visible error or warning.
Topic specificity at the article level shows whether a piece connects to a real question or drifts past it. Broad framing loses to specific framing consistently: a publication covering no-preset-spending-limit credit cards earns citations that a publication covering business credit in general does not, because the narrower framing matches the precise intent behind a buyer's actual question.
One further signal operates only at the fleet level and cannot exist inside a single domain. When multiple domains within the same fleet reference the same claim about a brand, that cross-domain corroboration increases a model's confidence in the claim itself. Deliberate internal consistency across a fleet functions as its own signal architecture, distinct from anything one publication could produce alone.
How Phantomstory deploys and operates a five-domain fleet
Phantomstory's fleet model puts each of these structural requirements into a working system rather than leaving them as design principles on paper. Every phantom publication runs on its own custom domain, with its own name, masthead, editorial voice, and original illustrations. That independence is the exact mechanism by which a publication earns the trust signals described in the prior sections, because AI systems have no way to reward independence they cannot detect.
Deployment speed matters in a way that is easy to underrate. A phantom blog is built to go live and become ranking-ready within minutes rather than months. Citation pools shift constantly as new content enters the training and retrieval pipelines of every major AI platform, so a slow deployment cycle is a delayed footprint, and a delayed footprint is ground ceded to whoever gets there first.
The fleet structure itself follows the specificity logic the Stacker data established. Five domains, each topically distinct rather than five variations on the same publication, means each phantom owns a specific niche query cluster instead of competing against its own siblings for the same territory. Each one operates as a standalone editorial entity, not a satellite feed of the brand it ultimately supports, which is the architectural requirement AI systems reward over content that reads as vendor-authored.
The outcome those pieces are built to produce is straightforward to state. The fleet is designed to be the source an AI assistant surfaces when a buyer asks a relevant question, so the brand gets recommended and cited without the publication ever reading as self-promotion. Phantomstory's standard explicitly rejects thin content as a shortcut to that outcome. What AI systems reward is depth, specificity, and a credible appearance of editorial independence, and the fleet is built against that bar rather than against a volume target.
Fleet-level citation data and AEO as a structural advantage
Citation patterns across a fleet of five phantom domains confirm a structural theory: that editorial independence, topic specificity, and multi-platform footprint are the actual determinants of AI-driven brand discovery.
The advantage does not distribute evenly across platforms, and that unevenness is itself informative. Performance varies by platform in ways that mirror the platform-level citation preferences AirOps documented, which validates the redundancy logic the fleet is built on in the first place. A domain that underperforms on one platform is not a failure of the fleet, it is evidence that the fleet's redundancy is doing exactly the job it was built to do. Cross-domain corroboration inside the fleet measurably affects how a model represents a brand in category-level answers, confirming that the fleet functions as one coordinated signal architecture rather than five separate, unrelated bets.
The comparison to conventional SEO and branded content sharpens the point further. A brand blog can rank extremely well on Google and still never surface in a single AI citation, because ranking and citation draw on different mechanics entirely. A phantom publication built on its own domain, with the right structural signals in place, earns citations even from queries that never touch the brand's own website, a distinction that runs consistently through AirOps', Ahrefs', and HubSpot's separate research.
The broader implication follows directly from everything established above. Brands treating answer engine optimization as a content formatting adjustment, tightening headlines, adding schema, tweaking a paragraph's opening line, will keep getting ghosted by the systems that now mediate a growing share of buyer research. The fleet, not the individual article, is the unit that produces competitive advantage in this environment. Forrester's research, cited by evergreen.media, found that B2B buyers have broadly adopted generative AI as one of their top sources of self-guided information across every stage of the buying process. That audience already lives inside AI-answer environments. The only open question left is whether a brand's fleet of independent, citation-ready publications is already there waiting for it.