Why AI Systems Discount Vendor-Authored Content
AI systems cite earned media over vendor content regardless of writing quality.
September 30, 2026
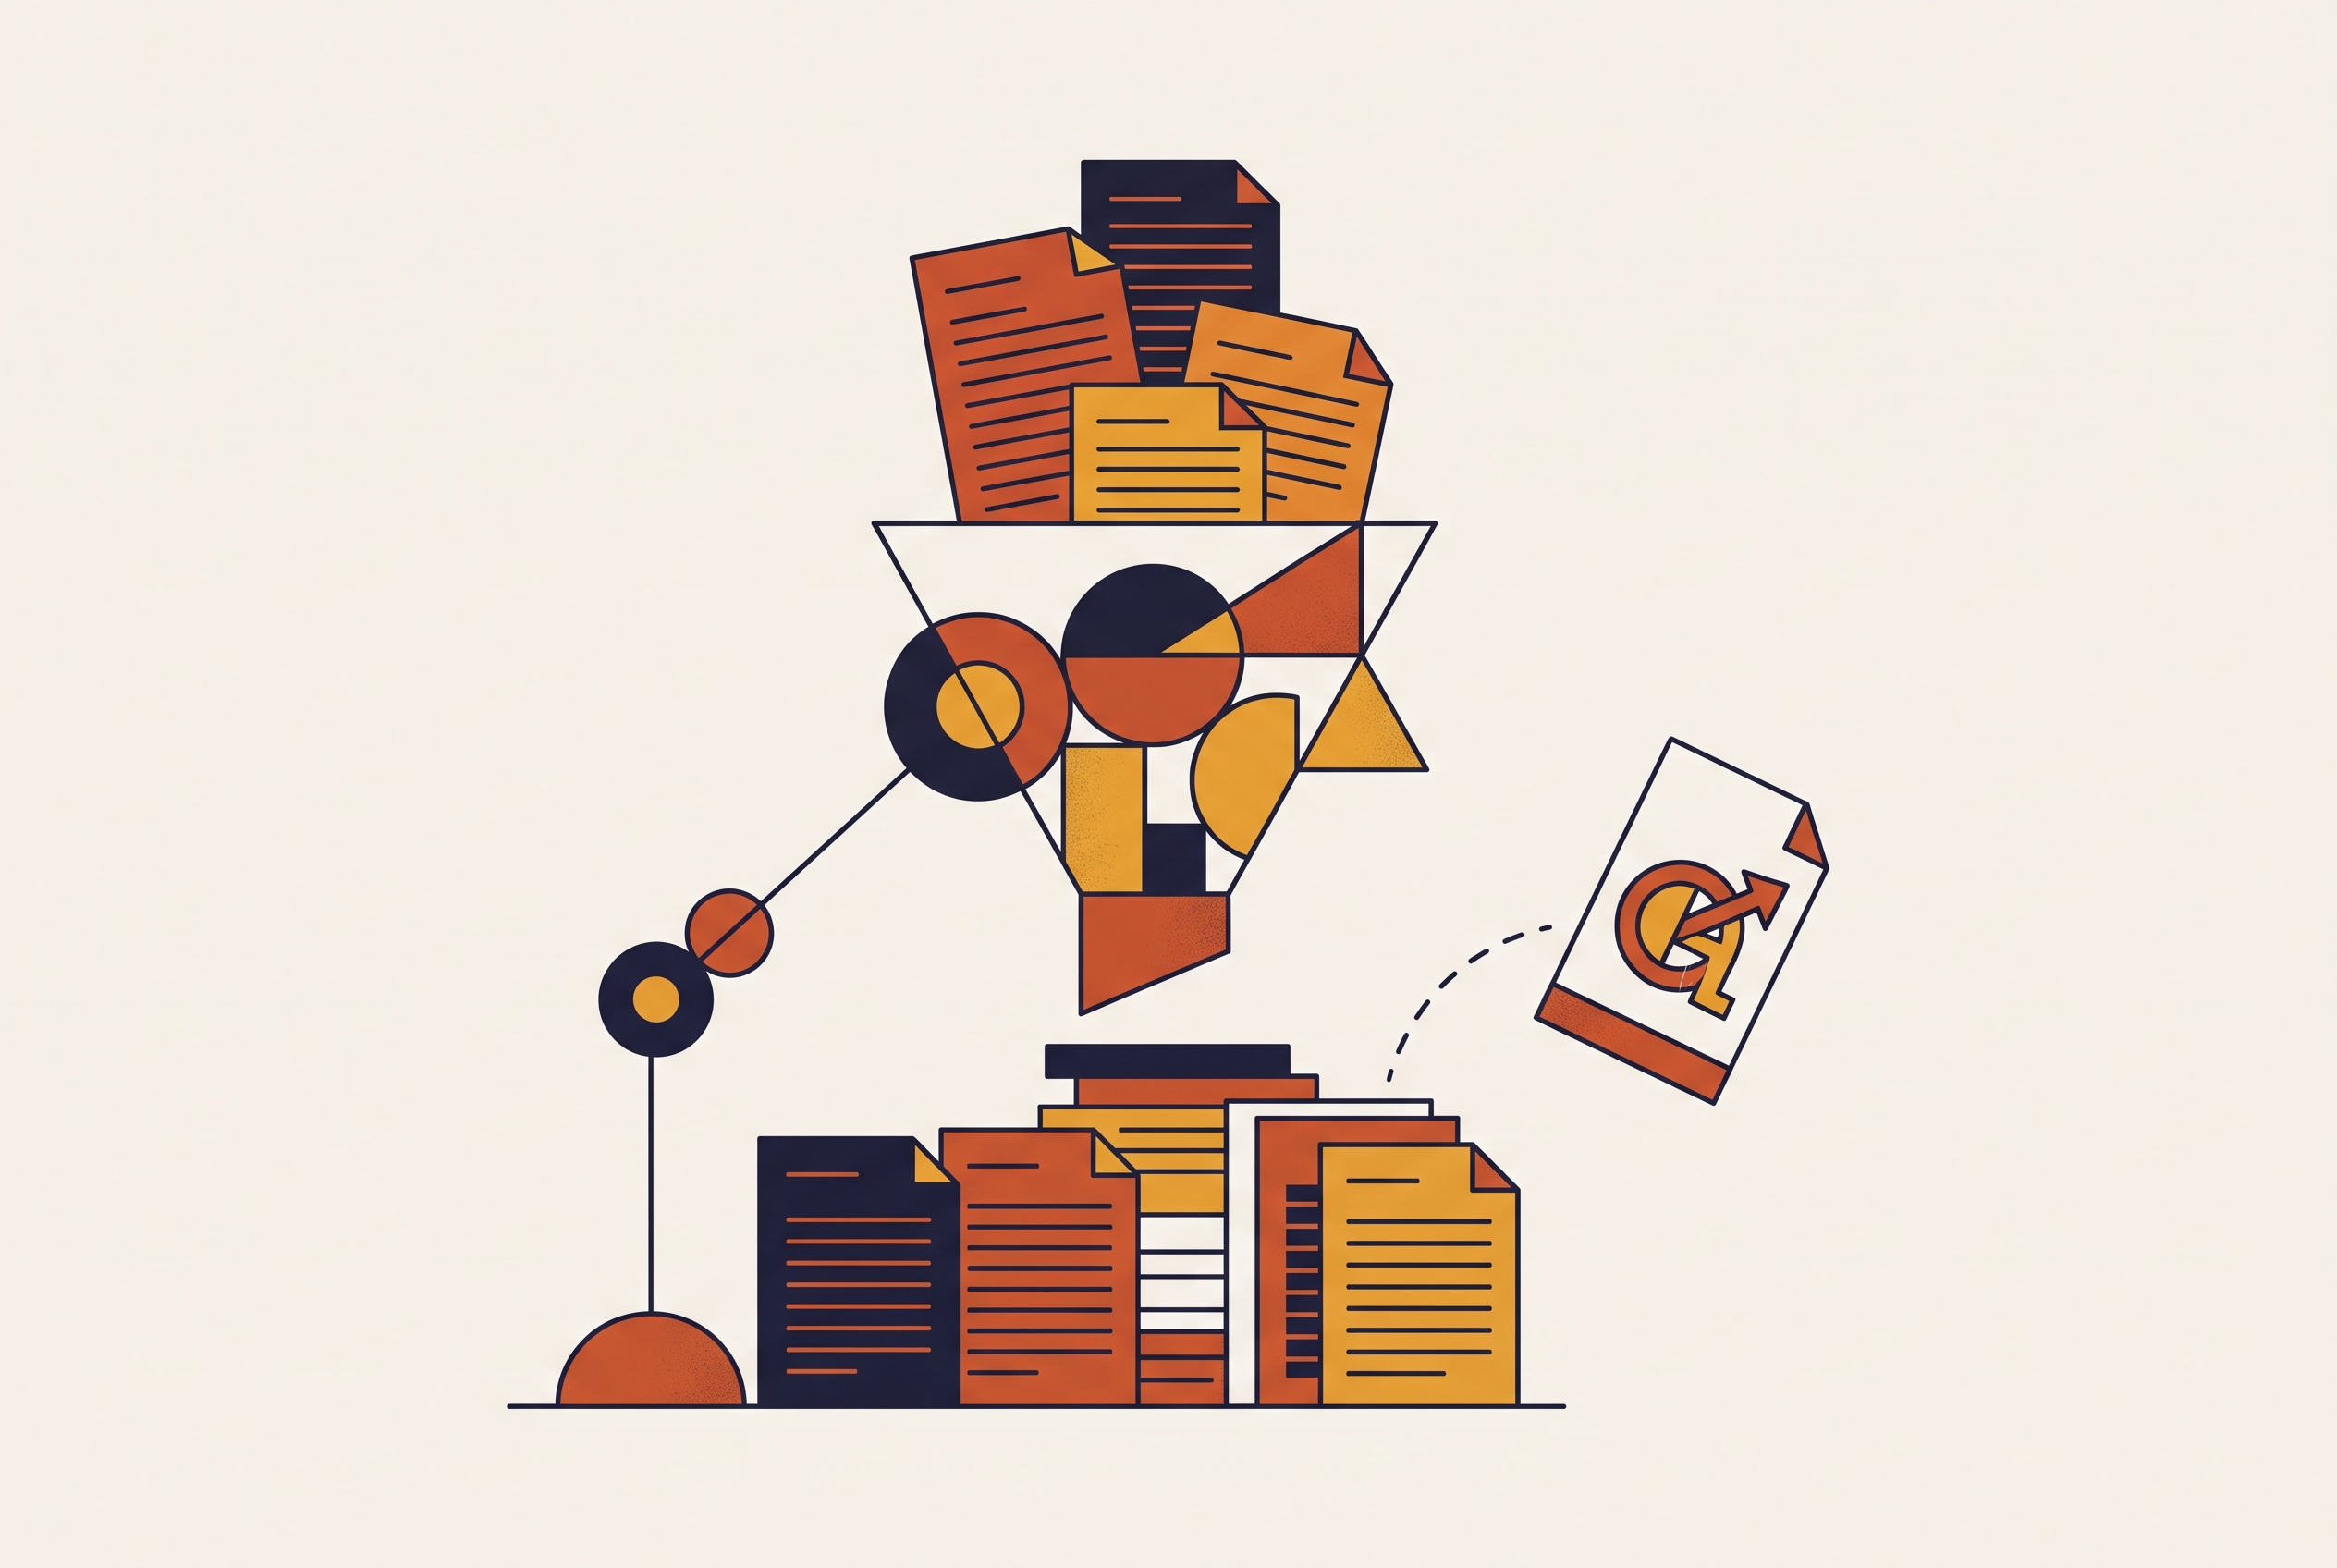
Someone asks ChatGPT whether a piece of software supports single sign-on, or whether a given vendor is any good, and gets back a clean paragraph with a citation or two attached. That answer did not come from the model's memory. It came from a retrieval pipeline running underneath the conversation, and the mechanics of that pipeline decide which pages get named and which get ignored entirely.
The process runs in three stages. The system retrieves a batch of candidate pages, pulls out the passages that look relevant, and stitches a response together from whatever survives that filtering. The sources that end up cited are simply the pages whose extracted passages did the most work in that final synthesis.
Getting cited, then, requires clearing three separate hurdles in order: the page has to be retrieved in the first place, it has to contain a passage that answers the question cleanly, and it has to carry signals the system reads as trustworthy. A page can clear the first two and still fail the third. A brand blog can be indexed, show up in the candidate set, and contain a paragraph that answers the question exactly, and still never get cited because it fails the trust filter that runs after retrieval.
The unit being judged is smaller than most content teams assume. Anthropic's own documentation on web search describes each citation as carrying only a short excerpt of the source text, not a full page or even a full section. That means a page answering one question in one tight paragraph will beat a page that spreads the same answer across four paragraphs buried in a longer post, regardless of which one is better written overall.
None of this is specific to one company's product. ChatGPT, Perplexity, Google AI Overviews, and Claude all apply variations of the same retrieve-extract-generate sequence, the AirOps AEO guide notes, making this pipeline platform-agnostic in its core logic. The interfaces differ. The underlying logic that decides who gets quoted does not.
Where commercial motive enters the trust-scoring step
The trust-signal step is where vendor content runs into trouble, and it runs into trouble for a specific, traceable reason: commercial motive is legible to the system. Third-party editorial coverage carries a positive trust signal. Content published by a company with a financial stake in the answer does not carry that same signal, no matter how accurate the content happens to be.
This is not speculation about how the models "feel" about vendors. A study by Chen et al., analyzing citation patterns across multiple industry verticals, found a systematic and overwhelming bias toward earned media over brand-owned and social content. Kumar et al., publishing the same month, put it in blunter terms: generative engines heavily weight earned media and often exclude brand-owned and social platforms outright, and even high-quality pages may not be cited if they live solely on a vendor's own blog. Quality of writing is not the variable under test. A well-argued, well-sourced vendor post loses out for the same reason a sloppy one does: the domain it lives on is the disqualifying signal, not the sentences on the page.
Muck Rack's 2026 analysis of citation links across ChatGPT, Claude, and Gemini backs this up at scale. Muck Rack's 2026 analysis of cited links across ChatGPT, Claude, and Gemini found that the overwhelming majority of all AI citations trace back to earned media sources, not owned content, paid ads, or SEO pages.
There is one real exception, and naming it keeps the argument honest. Capability queries, questions like whether a product supports SAML or handles a specific integration, are where vendor-owned content holds its strongest ground. Technical documentation gets cited directly in these cases because the motive to misrepresent is lower and the specificity of the answer is high. The claim is not that vendor content never gets cited, but that it gets structurally excluded from precisely the query categories, comparisons, trust checks, competitive evaluations, that dominate how buyers actually research a purchase.
Costs of AI answer exclusion
Exclusion from AI citations is becoming more expensive by the year, because the share of research that never results in a click to any website keeps growing. SparkToro's research found that a large majority of U.S. Google searches now end with no click to any website at all, and that rate climbs even higher on queries where an AI Overview appears. BrightEdge tracked a meaningful drop in average organic traffic for pages that had previously ranked in top positions, once Google's AI Overviews started appearing on those same queries.
Run the same dynamic in reverse and the number gets sharper. ALM Corp's analysis found that brands cited by AI Overviews earn 91% more paid clicks than brands that go uncited. Citation isn't a vanity metric measuring how visible a brand feels. It functions as a direct lever on paid acquisition costs and conversion, making exclusion a revenue problem.
The trend line points in one direction. HubSpot's Consumer Trends Report found that the majority of consumers plan to lean on AI more heavily when shopping going forward. Every year that share grows, the compounding cost of sitting outside the citation set grows with it. A brand excluded from AI answers today loses more than a fixed amount of visibility. It's losing a share of a market that keeps expanding underneath it.
None of this is a search-engine-optimization problem in the traditional sense. A page can rank fine and still never be the one an AI system decides to quote. The failure sits one layer downstream of ranking, in a filter that ranking algorithms were never built to satisfy.
Writing better content on a vendor blog does not fix the structural problem
Since the discount applied to vendor content is a function of who published it rather than how well it was written, sharpening the prose on a brand blog does nothing to change the signal the system uses to filter that content out. Kumar et al. said it without qualification: even high-quality pages go uncited if they live solely on vendor domains. The disqualifying factor is the domain and the commercial relationship it signals, full stop, not the argument constructed inside the post.
The order of operations makes this concrete. The RAG pipeline does not read a page's content and then decide whether to trust the source. Trust signals, the domain, the author, the editorial context surrounding the piece, get applied as retrieval filters before any passage extraction happens. A vendor page can be filtered out of contention before the system ever evaluates a single sentence of it. Rewriting that page more clearly doesn't help, because the system never gets far enough to notice the improvement.
This is where the standard SEO instinct leads brands astray. The reflex is to double down on the owned content program: publish more, publish better, optimize the headers. AirOps's AEO guide notes that a page can rank well in traditional search and still never appear in an AI response, and the SEO reflex of investing in the owned content program actively misleads here. Ranking and citation are two different systems answering two different questions, and improving one does not move the other when the barrier sitting between them is source trust rather than discoverability.
The capability-query exception described earlier doesn't undercut this; it confirms it. Vendor documentation earns citations in that narrow lane precisely because technical specs carry less perceived motive to mislead than marketing copy does. That foothold doesn't extend to the comparison pages, the trust-intent questions, or the competitive evaluations that make up most of what buyers actually ask an AI system during the research phase of a purchase. A company can maintain the best documentation in its category and still be invisible on every question that begins with "is this any good" or "how does this compare to."
How third-party sources shape brand answers
Ask an AI system about a vendor's pricing, its feature set, or how it stacks up against a rival, and the answer it produces gets shaped by the ecosystem of independent content that already exists around that product, not by anything the company itself has published. Muck Rack's 2026 analysis established that the overwhelming majority of AI citations trace to earned media, and the arXiv study on citation patterns (Chen et al., September 2025) confirms that independent editorial coverage carries a positive credibility signal that brand-owned content structurally cannot replicate.
There's a compounding effect layered on top of this. Seer Interactive's analysis of a large sample of LLM responses found that brands already mentioned somewhere in an LLM's training or retrieval corpus get cited at a rate roughly five times higher than brands with no prior mention at all. The system is, in effect, surfacing what it already recognizes from repeated, attributed mentions across independent sources. A brand with zero third-party footprint starts from a real disadvantage before a single query is ever run against it.
Distribution appears to matter as much as the content itself. A controlled study run by Stacker and Scrunch found that pushing the same content out through third-party news outlets increased AI citation rates dramatically compared to publishing that content only on an owned channel. Ahrefs, separately, found that brand mentions across the web correlate roughly three times more strongly with AI visibility than backlinks do, a 0.664 correlation versus 0.218, with YouTube mentions carrying an even stronger relationship. Backlinks were the currency of traditional SEO.
Format plays into this too. GenOptima's AI Brand Visibility Report, built on analysis of more than 2,500 domains cited by AI search engines, found that listicle-format content, structured "Top N" rankings and comparisons, accounts for 59.5 percent of all cited URLs. Product pages and standard blog posts make up a small fraction of the total by comparison. A brand pouring its budget into product pages and a corporate blog is competing against an entirely different content format, one it cannot credibly produce about its own category without triggering the same self-interest discount discussed earlier.
Community sources carry outsized weight in specific verticals. Aleyda Solis's analysis of SaaS citation patterns found that community and social domains account for the largest share of the mention-weighted top cited sources, ahead of news outlets and review sites, and Reddit turned up in every SaaS citation panel she studied. Search Engine Journal's reporting found community and user-generated content among the leading citation categories across IT services, consumer goods, and communication services. For a niche brand, a single recap post on a small, well-indexed industry Substack can carry more retrieval weight than a generic high-authority backlink from an unrelated domain.
Owning independent trade publications as a structural response
The discount runs on source identity rather than content quality. The only durable fix is to become the kind of source these systems already trust by publishing as an independent editorial operation rather than as a brand. The logic runs straight out of the retrieval pipeline described earlier: a standalone publication with its own domain, its own editorial identity, and its own byline gets processed by the RAG system as an independent source, whatever entity happens to fund it.
That is not a loophole in the system. It is the same dynamic that makes an industry analyst's report more citable than a vendor's white paper, or a trade magazine's review more citable than the same product's own landing page. Editorial independence functions as a real, structural signal inside the retrieval process.
There is room to move here, even in crowded categories. Conductor's analysis of publishing brand citations found that in Consumer Lifestyle, no single publisher commands an outsize share of the citation pool. A focused independent site can break into that mix without having to dislodge an entrenched incumbent first, because no incumbent holds the kind of lock that would make entry pointless.
The format advantage stacks on top of the structural one. Independent publications can produce the listicle, comparison, and "Top N" formats that GenOptima's data shows account for the majority of AI-cited URLs, formats a brand blog cannot credibly run about its own competitive category because of its own financial stake in the outcome.
Phantomstory's phantom publication model follows this reasoning directly. Each phantom operates as a standalone trade publication on its own domain, with its own name, its own editorial voice, and original reporting, built to carry the trust signals AI systems reward and to produce the formats those systems cite most often. It is a structurally independent source that happens to be owned and operated by the brand it covers, the distinction the entire retrieval pipeline is built to reward.
Because ChatGPT, Claude, and Perplexity all preferentially cite independent sources over vendor-owned pages, a phantom publication enters the citation ecosystem as a peer of the outlets already dominating it, rather than as a brand asset competing against that ecosystem from the outside. And because Seer Interactive's corroboration threshold means citation rates compound as independent mentions accumulate, a phantom that goes live and gets indexed early builds that accumulated presence well ahead of competitors who wait.
None of this argues that vendor content is worthless. Documentation still earns citations on capability queries, and a well-run brand blog still serves purposes beyond AI visibility. The argument is narrower and harder to dispute: vendor content is the wrong tool for the specific job of AI-era discovery, for structural reasons that no amount of better writing resolves. The tool that fits the job is ownership of the independent sources these systems are already built to trust.